Invisible Failures
Production issues surface as symptoms, not signals. Teams know something is wrong, but the system gives no clear indication of where the failure actually originates.
Get end-to-end visibility into your Go performance with application monitoring tools. Gain insightful metrics on performance bottlenecks with Go monitoring to optimize your application.
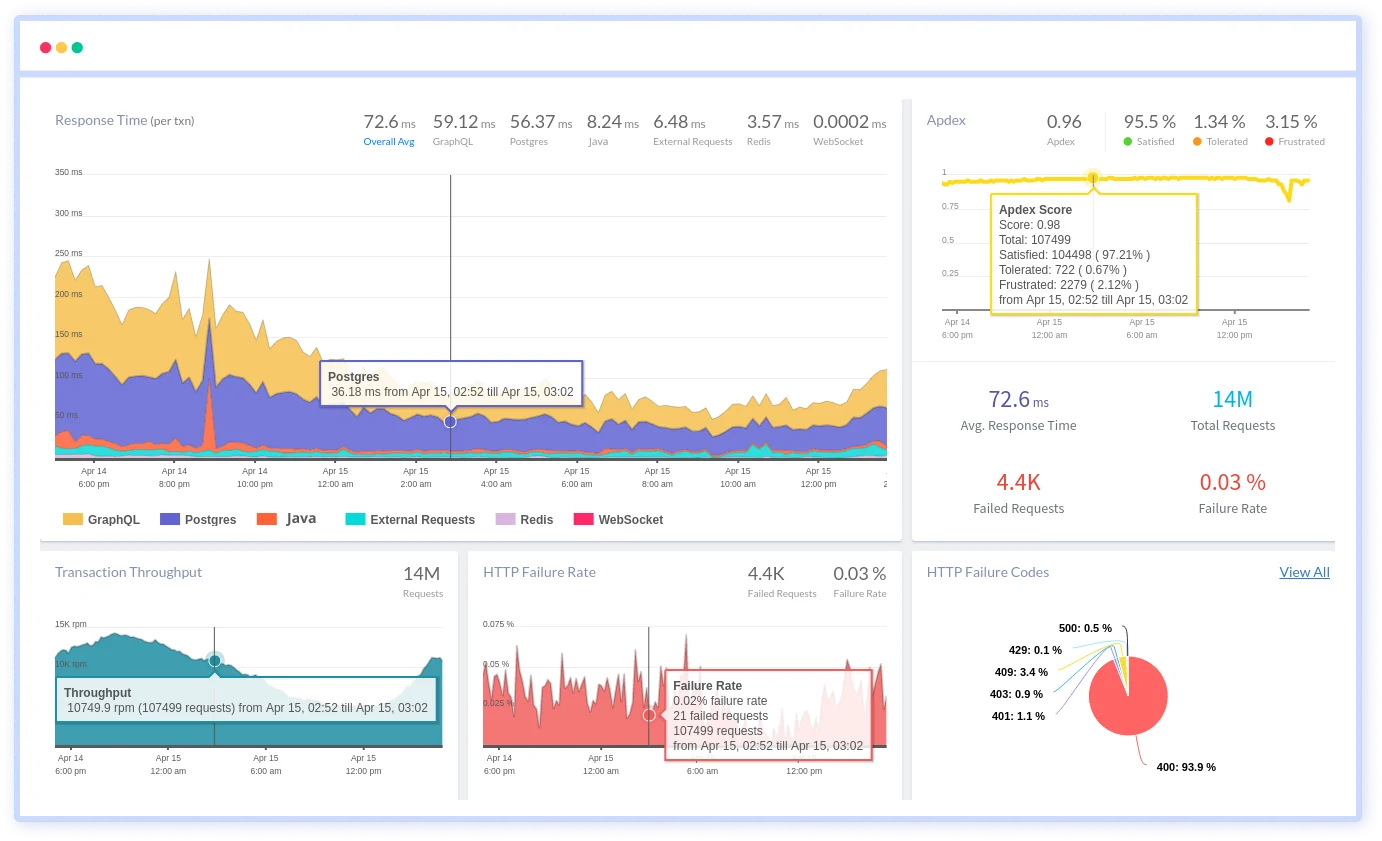
Production issues surface as symptoms, not signals. Teams know something is wrong, but the system gives no clear indication of where the failure actually originates.
Logs, metrics, and traces exist in isolation. Engineers are forced to mentally reconstruct execution paths across services, versions, and environments.
Incidents consume senior engineering time because identifying the first breaking point takes longer than fixing the actual problem.
Go’s concurrency model hides timing and contention problems until traffic spikes. Failures appear non-deterministic and hard to reproduce.
Systems behave well at low load but degrade unpredictably at scale. Teams lack confidence in how code paths respond under real production pressure.
When multiple services interact, no team can clearly say where responsibility starts or ends, leading to stalled investigations.
Production signals exist, but they lack hierarchy and meaning. Engineers see activity without knowing which changes actually explain user impact or failures.
There is plenty of data, but not enough direction. Engineers spend time filtering information instead of understanding the failure.
Real-time visibility into Go services that helps engineering teams maintain speed, stability, and predictable production performance.
Follow each request across APIs, microservices, databases, and background workers in a single distributed trace. Understand execution flow and performance behavior across your Go application.

Visualize how Go services communicate with databases, message brokers, caches, and external APIs. Quickly detect latency bottlenecks, traffic shifts, and failure patterns across your architecture.

Keep a close watch on essential workflows such as API processing, order handling, and background tasks. Identify slow transactions, rising error rates, and performance regressions before users notice.

Monitor third-party services and integrations your Go applications depend on. Catch slowdowns and outages early to avoid cascading system issues.


Atatus fits teams that value directness and accuracy. It integrates into engineering workflows without changing how teams think or work.
Teams quickly understand what is happening in production without stitching together multiple mental models.
Engineers can start trusting production signals without weeks of onboarding or internal evangelism.
Platform, SRE, and backend teams operate from the same understanding of system behavior during incidents.
Release rollbacks, mitigations, and fixes are based on evidence, not guesswork or intuition.
Issues are resolved at the right level, reducing dependency on a few senior engineers.
Production behavior becomes explainable, even as traffic patterns and workloads evolve.
Engineers believe what the system tells them, which shortens investigations and reduces debate.
Teams stay prepared for failure modes they have not explicitly seen before.
Less time spent firefighting allows teams to invest energy into stability and architecture improvements.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineersPricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
The Go performance monitoring tool helps developers to optimize the Go server performance.
A good Go APM solution answers the following two questions:
You can easily use application performance monitoring tools to answer, detect and resolve the above issues before they could impact the end users.
In general, there are two types of monitoring:
Every organization should have a well-implemented Go APM solution, which allows DevOps teams (and the organization as a whole) to resolve issues and performance bottlenecks efficiently and reduce Mean Time To Resolution (MTTR). This has a substantial impact on the bottom line of the business.
Now organizations do not have to deal with the unnecessary work involved in maintaining an extensive software analysis group.
Your Go performance monitoring tools should be easy to use, offer actionable insights, and be able to:
Technical Benefits:
Business Benefits:
With the help of the database monitoring, you can easily identify the database performance bottlenecks.


