Faster Deployment
Install the agent, get your first trace. No professional services engagement, no 30-day onboarding project.
One unified observability layer across infrastructure, services, logs, traces, and deployments, so your team ships faster and debugs in minutes, not hours.
From Signal to Root Cause in One Place. Atatus automatically correlates every metric, trace, rootcause event, and deployment so your team has full context at the moment of truth.
Distributed Tracing: Trace every request end-to-end across all services with full latency breakdown.
Service Dependency Maps: Live topology maps that show how every service connects and where errors propagate.
APM & Performance: Deep application performance monitoring with transaction-level visibility.
Log Correlation: Logs linked automatically to traces and infrastructure zero manual correlation.
Intelligent Alerts: Context-aware alerting that groups related signals and cuts alert fatigue.
Kubernetes Visibility: Full pod, node, and container observability for containerized workloads.
Every feature is designed around real engineering team workflows, not generic dashboards.
When a transaction slows down or fails, you need to see exactly which service, which call, and which line of code caused it. Atatus distributed tracing gives you a complete waterfall view across all your microservices without any manual instrumentation work.
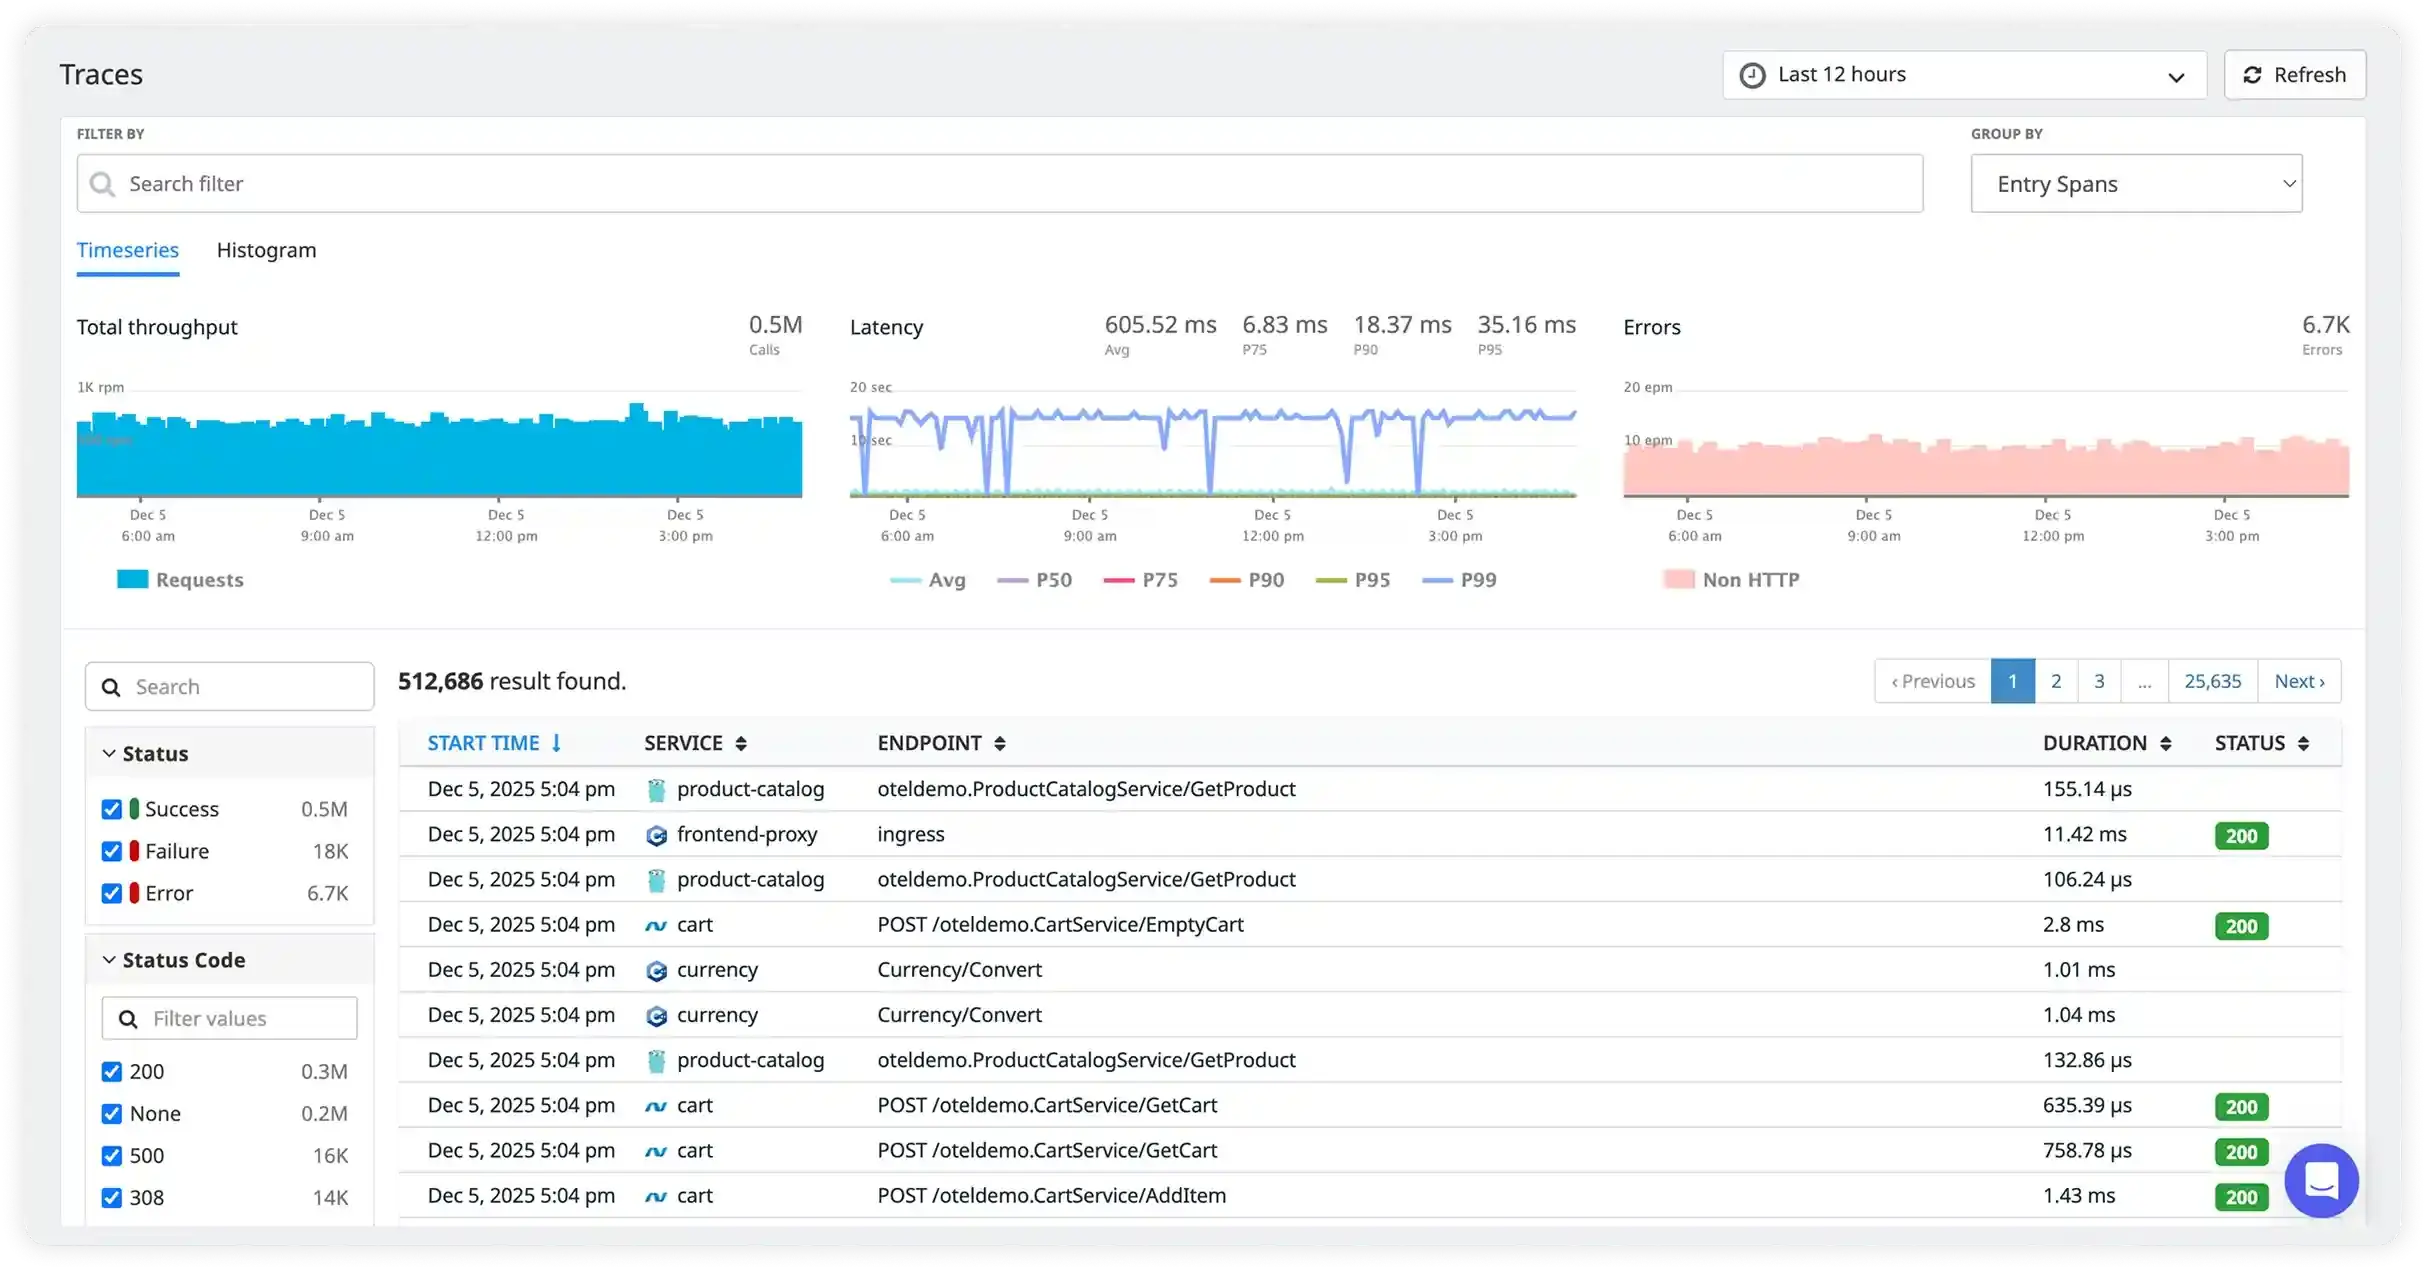
Atatus automatically discovers and maps every service-to-service relationship in your environment. When something breaks, you instantly see the blast radius which services are affected and which upstream caller caused it.

Atatus correlates traces, logs, metrics, and deployment history automatically so your team arrives at the root cause in minutes, not after an hours-long investigation across multiple tools.

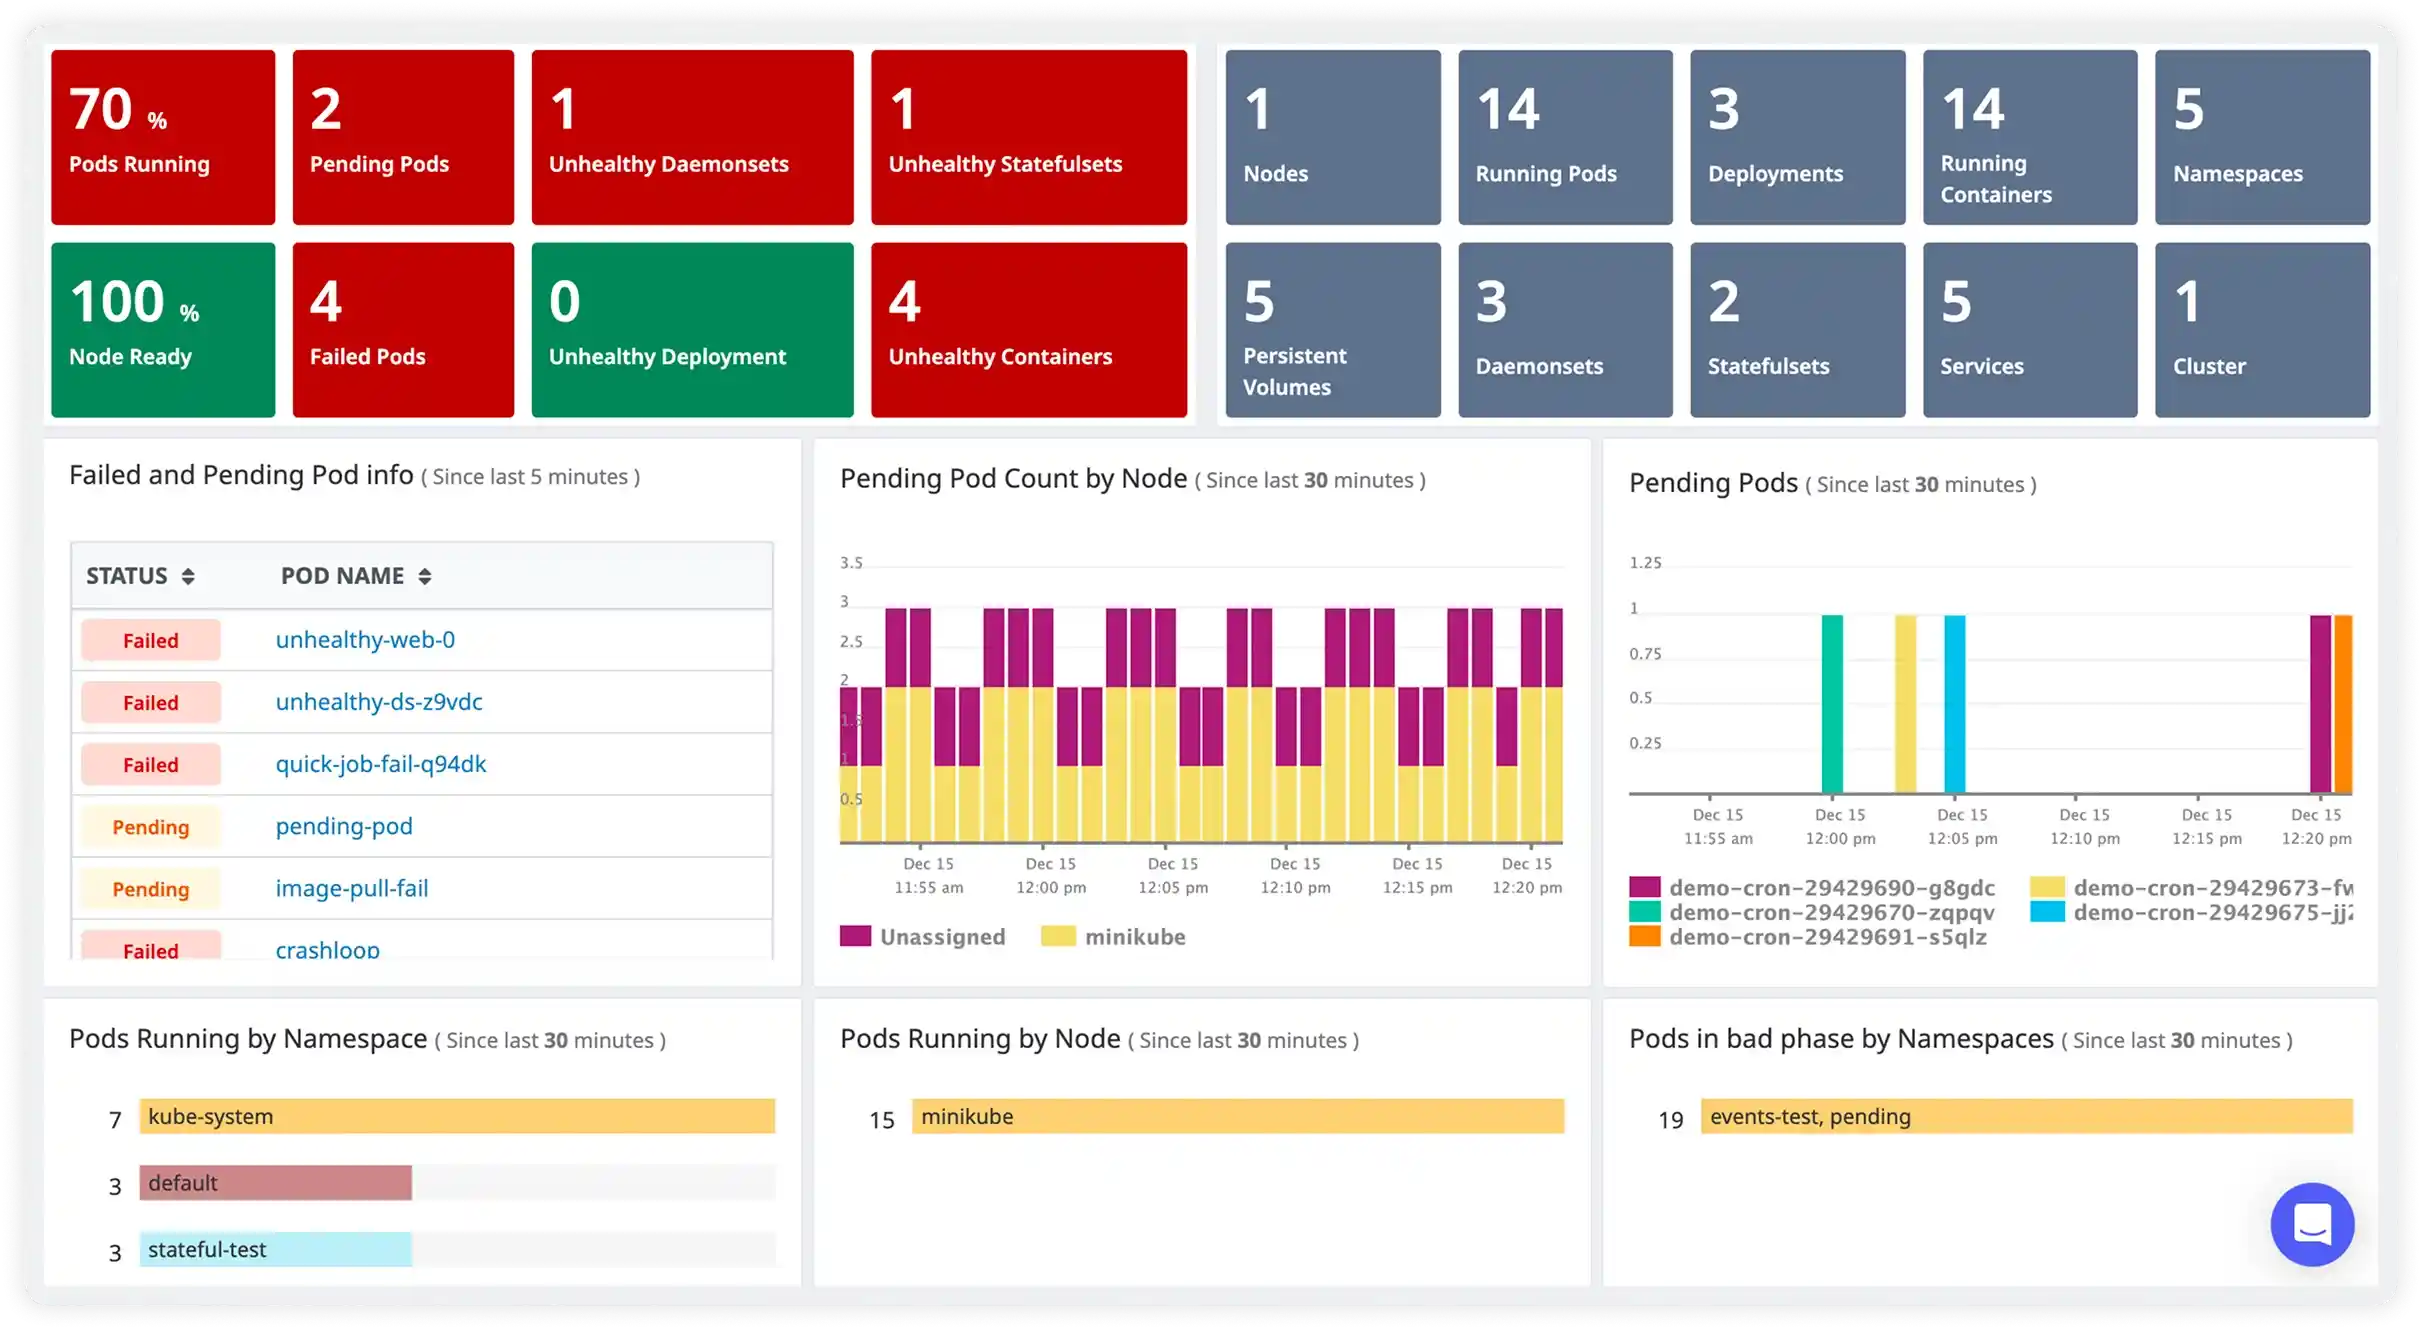
Atatus goes beyond surface-level Kubernetes metrics. Every pod event, resource pressure, and OOMKill is automatically linked to the traces and logs happening inside those containers, giving your team context that K8s dashboards alone can never provide.
Atatus customers don't just get better dashboards. They get measurable engineering and business outcomes.
Teams using Atatus resolve incidents in minutes, not hours, thanks to automated root cause correlation.
Intelligent alert grouping reduces noise so on-call engineers focus only on signals that matter.
Unified deployment tracking and real-time performance feedback shortens release cycles.
Proactive alerting and anomaly detection help teams maintain high availability across all services.
Infrastructure correlations surface over-provisioned resources and help right-size your Kubernetes clusters.
Install the Atatus agent and have your first traces and metrics flowing in under 10 minutes.
Install the agent, get your first trace. No professional services engagement, no 30-day onboarding project.
Predictable, volume-based pricing with no hidden data ingestion fees or per-seat penalties for large teams.
Built on open standards. Your existing OTel instrumentation works out of the box.
APM, infrastructure, logs, traces, and real user monitoring correlated in a single pane of glass.
For teams with strict data residency or compliance requirements, Atatus offers full on-premises deployment.
Atatus doesn't just show you what happened. It tells you why, and suggests what to do next.
Pre-built integrations for tools your team already uses. Connect in minutes, not days.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineers"Solid Product even better support." The integration path is incredibly simple/easy and the overall interface is very intuitive. That said, I had a handful of odd use cases that the support team was incredibly responsive in helping me work through.
Pricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
Yes. Atatus provides APM, distributed tracing, infrastructure monitoring, log management, and real user monitoring in a single platform. Most teams replace 3–5 tools. You get deeper correlation between signals and significant cost savings without sacrificing coverage.
Atatus supports all major cloud providers (AWS, GCP, Azure), container orchestration platforms (EKS, GKE, AKS, self-managed K8s), and application runtimes including Node.js, Python, Java, Go, Ruby, PHP, and .NET. OpenTelemetry support means your existing instrumentation works out of the box.
Atatus automatically correlates traces, logs, metrics, and deployment events so that when an alert fires, you already have the context you need. Deployment correlation links performance regressions to the exact release, and related events are grouped into a single incident view — eliminating the manual investigation work that inflates MTTR.
Yes. Atatus includes deployment tracking that automatically correlates every new release with changes in error rates, latency, and throughput. You'll know within minutes whether a deployment improved or degraded performance before your customers do.
No manual instrumentation is required for most common frameworks. Atatus agents auto-instrument popular HTTP frameworks, database drivers, and messaging queues. For custom instrumentation or advanced use cases, we support the OpenTelemetry SDK so your developers work with open standards.
Atatus is purpose-built for microservices. Service dependency auto-discovery, distributed trace propagation across service boundaries, and per-service alerting thresholds are all designed for environments with dozens or hundreds of services.
Teams switching to Atatus from Datadog or New Relic typically report 40–70% savings on observability spend. We offer transparent, volume-based pricing with no per-host fees, no per-seat charges for viewers, and no data ingestion penalties for high-cardinality traces. Schedule a pricing consultation to get a custom comparison for your usage profile.
Microservices monitoring is the practice of collecting and correlating telemetry data such as metrics, traces, and logs from every service in a distributed application. Unlike monolithic app monitoring, it requires distributed tracing to follow requests across service boundaries and service maps to visualize dependencies. Without proper microservices monitoring, diagnosing failures becomes exponentially harder as your service count grows.
Yes. Atatus ingests telemetry from any OpenTelemetry-instrumented service alongside its own agents. You don't need to re-instrument existing services to use Atatus, point your OpenTelemetry collector at Atatus and your existing traces, metrics, and logs will flow through the platform immediately.
Start free and send your first trace with OpenTelemetry or the Atatus agents. APM, logs, RUM, infrastructure and SIEM, all on one timeline.