Lifecycle Phase Blindness
hapi requests move through onRequest, auth, validation, handler execution, and response phases. In production, teams cannot see which lifecycle phase actually introduced latency or failure.
Get end-to-end visibility into your Hapi performance with application monitoring tools. Gain insightful metrics on performance bottlenecks with Node.js monitoring to optimize your application.
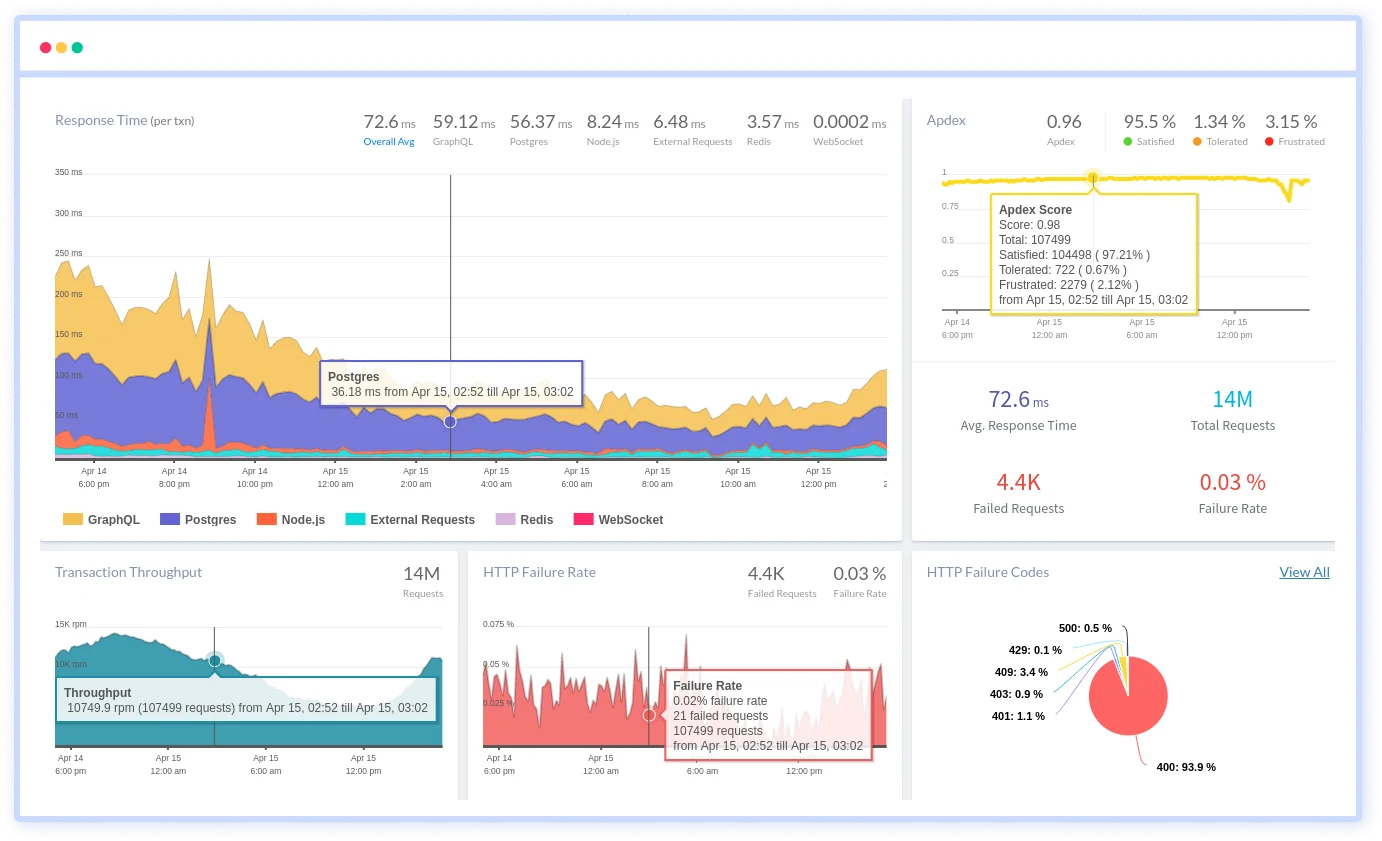
hapi requests move through onRequest, auth, validation, handler execution, and response phases. In production, teams cannot see which lifecycle phase actually introduced latency or failure.
Multiple extensions attach to the same lifecycle events. Under real traffic, the execution order and cumulative cost of these extensions become unclear.
Authentication strategies execute early and conditionally. When auth slows down or fails, engineers struggle to attribute impact to specific strategies or hooks.
Payload and query validation behave differently as request sizes and data shapes grow. Validation overhead silently increases without clear attribution.
Async handlers and pre-handlers resolve independently. When execution stalls, teams lose visibility into which async boundary delayed the response.
Shared services are injected across handlers and extensions. Under load, it becomes difficult to tell which dependency introduced blocking or contention.
At higher concurrency, lifecycle timing changes. Code paths that appear stable in staging behave differently when event loop pressure increases.
Errors surface after lifecycle state has already mutated. By the time investigation starts, the execution context that explains the failure is gone.
End-to-end observability for Hapi workloads that helps teams understand traffic behavior, optimize route performance, and maintain reliable production systems.
Quickly surface which routes consume the most processing time under real traffic. Focus optimization efforts where performance impact is highest.

Measure how long each request takes across handlers, services, and dependencies. Uncover latency trends affecting user experience.

Visualize live production traffic volume, peak usage periods, and request distribution. Make data-driven decisions for scaling and optimization.

Compare route latency, throughput, and error rates based on real-world usage data. Identify underperforming routes and prioritize improvements effectively.


Engineering teams running hapi choose Atatus when understanding lifecycle execution matters more than counting requests or averages.
Teams reason about request behavior in terms of hapi lifecycle phases instead of flattened request timings.
Engineers understand how registered extensions interact, execute, and compound latency during real production traffic.
Asynchronous delays are exposed in context, allowing engineers to reason about timing instead of guessing.
Authentication behavior is evaluated as part of request execution, allowing teams to diagnose auth-related slowdowns without guesswork.
Teams identify when validation logic becomes a bottleneck as payload size, schema complexity, or traffic patterns change.
Async pre-handlers and handlers are understood as a continuous execution path, not isolated callbacks.
Injected services are evaluated in runtime context, helping teams detect blocking behavior and contention under load.
As concurrency grows, lifecycle execution remains explainable instead of degrading into timing anomalies.
During failures, teams rely on execution reality rather than reconstructing lifecycle flow from logs.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineersPricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
The Hapi performance monitoring tool helps developers to optimize the Hapi server performance.
A good Hapi APM solution answers the following two questions:
You can easily use application performance monitoring tools to answer, detect and resolve the above issues before they could impact the end users.
In general, there are two types of monitoring:
Every organization should have a well-implemented Hapi APM solution, which allows DevOps teams (and the organization as a whole) to resolve issues and performance bottlenecks efficiently and reduce Mean Time To Resolution (MTTR). This has a substantial impact on the bottom line of the business.
Now organizations do not have to deal with the unnecessary work involved in maintaining an extensive software analysis group.
Your Hapi performance monitoring tools should be easy to use, offer actionable insights, and be able to:
Technical Benefits:
Business Benefits:
With the help of the database monitoring, you can easily identify the database performance bottlenecks.

