Request Execution Ambiguity
Individual requests traverse complex code paths influenced by hooks, middleware, and runtime state. Without execution-level visibility, latency sources remain indistinguishable.
Get end-to-end visibility into your Drupal performance with application monitoring tools. Gain insightful metrics on performance bottlenecks with PHP monitoring to optimize your application.s
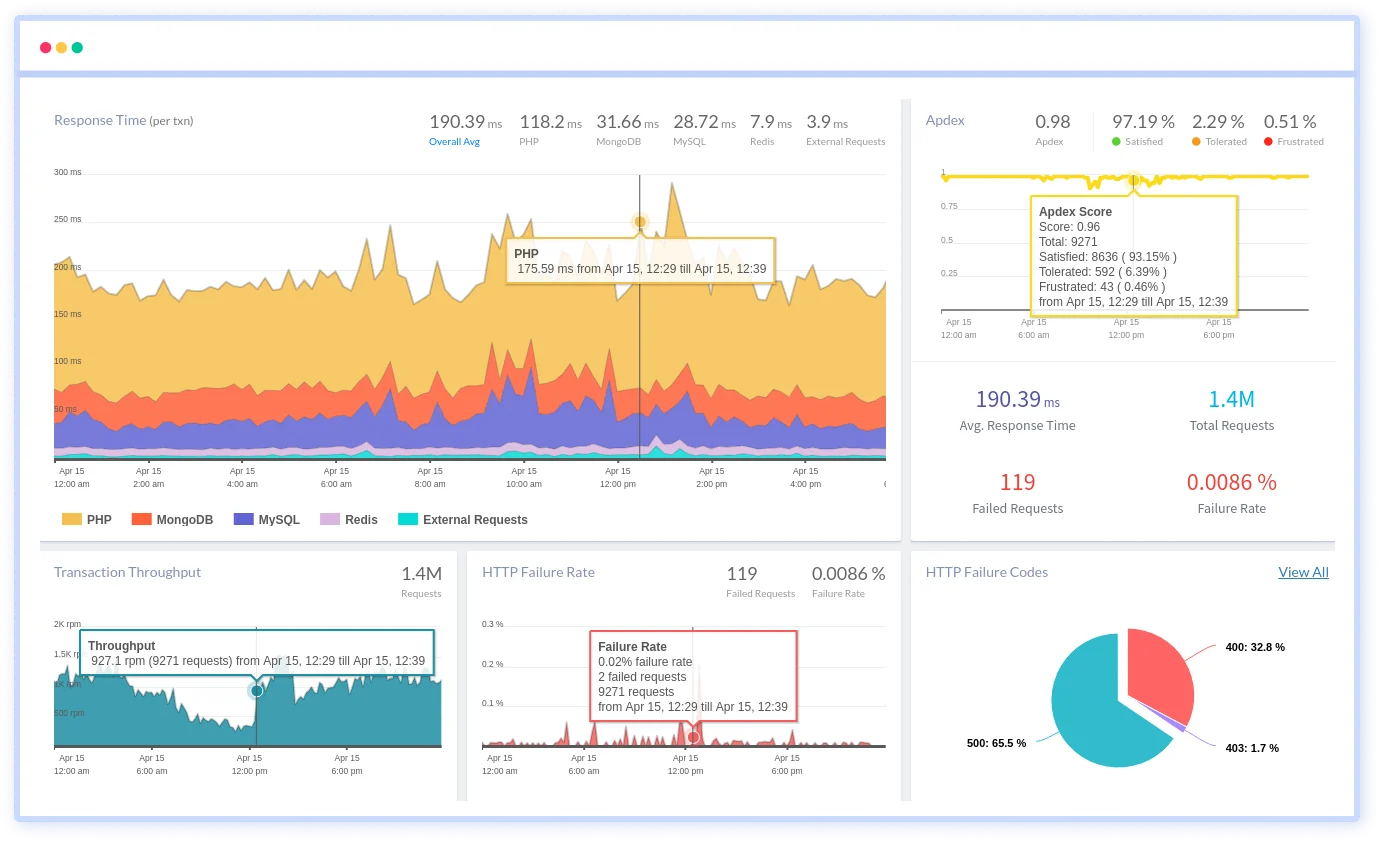
Individual requests traverse complex code paths influenced by hooks, middleware, and runtime state. Without execution-level visibility, latency sources remain indistinguishable.
Failures surface detached from their originating execution flow. Stack traces alone fail to explain why a request reached an invalid state.
Runtime data is disconnected across layers. Application behavior, PHP execution, and infrastructure pressure cannot be reasoned about together.
Investigations expand linearly with system complexity. Engineers iterate through assumptions instead of validating facts.
Traffic amplifies nondeterministic behavior. Edge cases dominate performance characteristics at scale.
Post-deploy regressions lack clear causality. Teams cannot confidently link performance changes to code changes.
Upstream and downstream dependencies affect execution timing unevenly. Their contribution is difficult to quantify during incidents.
Capacity and tuning decisions are made confidence-poor. Teams compensate with overprovisioning or reactive firefighting.
Real-time observability for Drupal that helps teams understand performance behavior, resolve issues faster, and maintain reliable production systems.
Follow every request across services, Drupal modules, databases, and background processes in a single unified trace. Understand execution flow and pinpoint latency across your entire Drupal stack.

Monitor database queries to surface slow executions, heavy loads, and inefficient access patterns. Optimize content delivery and backend performance with confidence.

Measure response times for third-party APIs, integrations, and external services. Identify slow dependencies before they impact user experience.

Capture full stack traces and rich contextual data for Drupal errors in real time. Resolve issues faster with precise root-cause insight.


Engineering teams adopt Atatus when system complexity outpaces intuition. The choice is driven by how quickly teams can form accurate mental models of production behavior and sustain confidence as systems evolve.
Teams reason about real request paths, not averaged abstractions. This shortens investigation cycles.
Engineers base conclusions on observed execution paths instead of inferred behavior. This removes ambiguity during performance analysis and incident response.
Insights are derived from live traffic patterns, not synthetic instrumentation assumptions.
Engineers engage without retraining workflows. Usage grows naturally across roles.
Engineers can reason about request behavior in the exact order hooks, subscribers, and middleware execute, instead of inferring impact from collapsed timings.
Errors are evaluated in the context of the hook, service, or event subscriber that mutated state, avoiding blame drift across modules.
After deployments, teams verify whether hook execution timing or ordering changed, rather than guessing which release introduced latency.
As contrib and custom modules stack, teams observe how hooks compound execution cost instead of treating performance as an averaged outcome.
Operational tuning is based on how hooks behave under real traffic and cache states, tightening the loop between code change and system response.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineersPricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
The Drupal performance monitoring tool helps developers to optimize the Drupal server performance.
A good Drupal APM solution answers the following two questions:
You can easily use application performance monitoring tools to answer, detect and resolve the above issues before they could impact the end users.
In general, there are two types of monitoring:
Every organization should have a well-implemented Drupal APM solution, which allows DevOps teams (and the organization as a whole) to resolve issues and performance bottlenecks efficiently and reduce Mean Time To Resolution (MTTR). This has a substantial impact on the bottom line of the business.
Now organizations do not have to deal with the unnecessary work involved in maintaining an extensive software analysis group.
Your Drupal performance monitoring tools should be easy to use, offer actionable insights, and be able to:
Technical Benefits:
Business Benefits:
With the help of the database monitoring, you can easily identify the database performance bottlenecks.


