Undetected Cache Fragmentation
Infinispan entries evict prematurely under hot partition skew. Second-level cache misses spike database load untracked. Platform engineers overprovision nodes without hit ratio baselines.
Get end-to-end visibility into your JBoss performance with application monitoring tools. Gain insightful metrics on performance bottlenecks with Java monitoring to optimize your application.
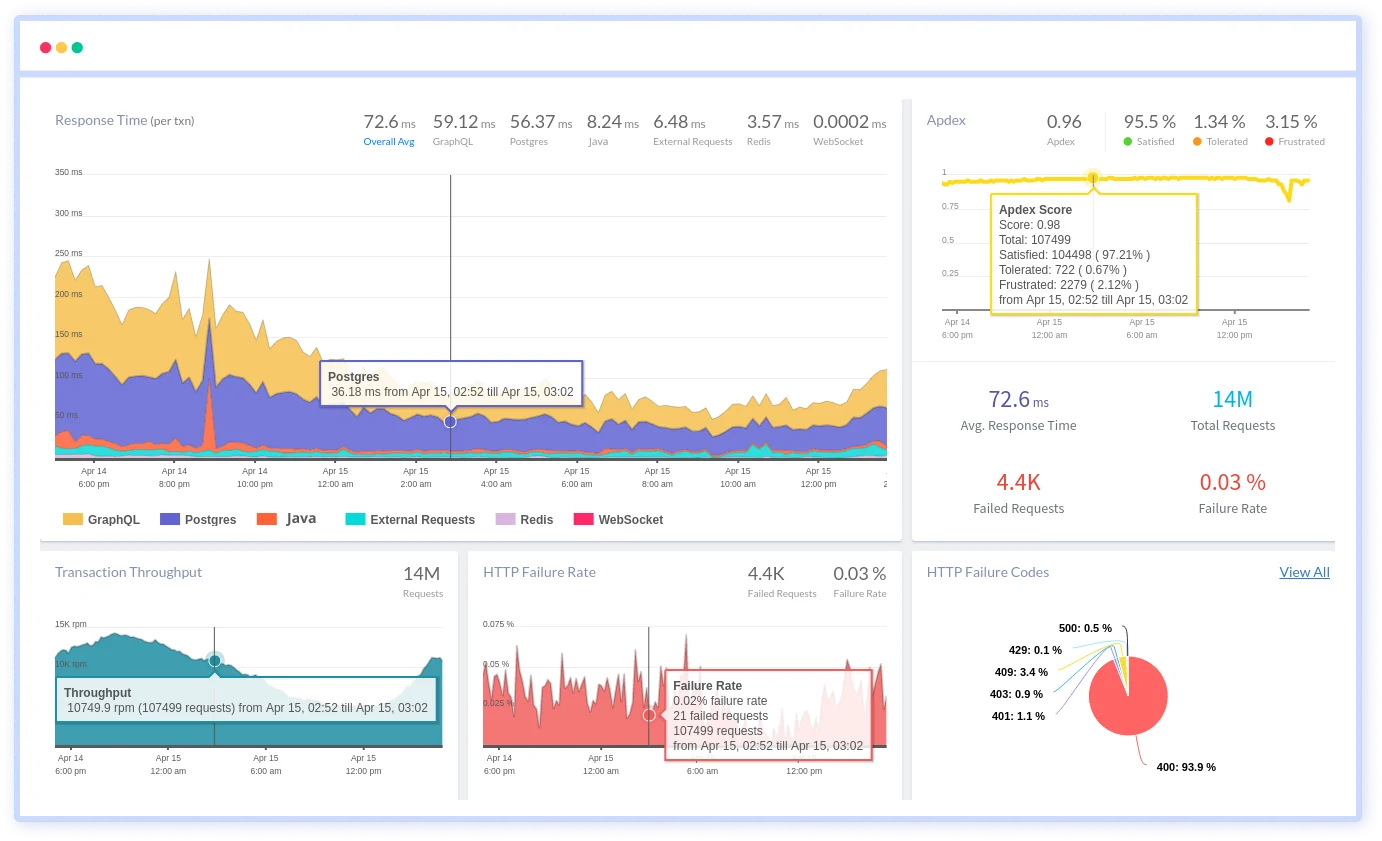
Infinispan entries evict prematurely under hot partition skew. Second-level cache misses spike database load untracked. Platform engineers overprovision nodes without hit ratio baselines.
HTTP/2 streams pile up in acceptor threads during burst concurrency. NIO poller exhaustion drops persistent connections. SREs tune blindly across multi-port configs.
JGroups multicast failures desync HA nodes without heartbeat profiles. Singleton deployments split-brain across partitions. Domain controllers mask member health until failover fails.
MDBs deadlock on XA transactions spanning multiple datasources. Thread dumps bury EJB container locks in noise. Backend engineers kill processes instead of breaking cycles.
Connection handles accumulate in JBossCLI data sources post-rollback. Max pool capacity hits zero under error storms. Platform teams recycle JNDI lookups without leak paths.
HornetQ persistence lags under high-volume producers without depth metrics. Message redelivery storms exhaust worker pools. SREs purge queues blind to consumer starvation.
Management realms lose audit trails across federated domains. CLI operations timeout without operation latency traces. Platform leads debug auth failures through console noise.
Connector metrics and thread states surface within seconds of agent attach. SREs correlate queue depth with JVM pauses instantly. Platform dashboards unify multi-instance health views.
Real-time observability for JBoss environments that helps teams understand request behavior, optimize processing flow, and resolve production issues faster.
Measure how long each request takes across servlets, handlers, and internal processing layers. Quickly uncover slow execution paths affecting response times.

Pinpoint performance slowdowns within specific request handlers and processing components. Focus optimization efforts where delays originate.

Monitor response times for dependent services, microservices, and external APIs. Detect latency introduced by downstream systems.

Capture detailed error context alongside correlated logs for every request. Debug faster with full visibility across errors, traces, and performance data.


JBoss teams choose Atatus to examine real production request execution directly, instead of inferring behavior from disconnected data or averages.
EJB metrics and undertow states surface cluster-wide post-attach. Platform controllers correlate node drifts instantly. HA health unifies across domain partitions.
JMX hooks instrument standalone and domain modes without standalone.xml edits. Backend fleets deploy without controller coordination. Full visibility hits prod Day Zero.
Transaction rollbacks map to exact interceptor chains in prod dumps. Developers repro XA failures with container-equivalent traces. Debugging flows match runtime exactly.
Infinispan skew and pool exhaustion pagers trigger at 90% thresholds. SREs get cross-node runbooks per partition. Domain noise collapses to validated risks.
Debugging relies on what actually executed during live traffic, not assumptions about server or application flow.
Runtime evidence reflects real concurrency, real data, and real load patterns seen only in production.
Failing and successful requests can be examined side by side using observed execution behavior.
Recurring production issues can be reviewed consistently without unreliable local reproduction attempts.
Release, rollback, and mitigation actions are taken using observed production execution rather than intuition.
Atatus adapts to how engineering teams work across development, operations, and reliability.
Debug errors and slow paths with the full context of what happened.
Atatus for developersTrack deployments and see how each release affects stability.
Atatus for DevOpsWatch latency and error rates to ship with less production risk.
Atatus for release engineersPricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
The JBoss performance monitoring tool helps developers to optimize the JBoss server performance.
A good JBoss APM solution answers the following two questions:
You can easily use application performance monitoring tools to answer, detect and resolve the above issues before they could impact the end users.
In general, there are two types of monitoring:
Every organization should have a well-implemented JBoss APM solution, which allows DevOps teams (and the organization as a whole) to resolve issues and performance bottlenecks efficiently and reduce Mean Time To Resolution (MTTR). This has a substantial impact on the bottom line of the business.
Now organizations do not have to deal with the unnecessary work involved in maintaining an extensive software analysis group.
Your JBoss performance monitoring tools should be easy to use, offer actionable insights, and be able to:
Technical Benefits:
Business Benefits:
With the help of the database monitoring, you can easily identify the database performance bottlenecks.


