Full Visibility Into Your AI Applications
Monitor every prompt, trace every chain, track every token. Atatus gives your team deep observability across all your LLM-powered products, in one unified platform.
Every step of every call.
Agents traced as a tree. Fold a branch, open a span, read what went in and what came out.
- 3.42 s
- 3.38 s
- 180 ms
- 1.06 s
- 270 ms
- 330 ms
- 1.54 s
Parallel tool calls start together. Fold a branch or pick a span · sample data
openai.chat
- Duration
- 1.06 s
- Tokens in
- 1,240
- Tokens out
- 96
- Cost
- $0.0041
system + user + 2 retrieved documentscall get_deploy_history and get_service_healthKnow where the tokens go.
Daily spend for the last 30 days. Pick a day to split it by model.
- gpt-4-turbo$109.4346%
- claude-3-opus$65.5228%
- gpt-3.5-turbo$30.5113%
- claude-3-sonnet$23.8210%
- gemini-pro$8.724%
Drag across the chart or use the arrow keys to pick a day.
Every model, side by side.
Sort the model breakdown, then tick two models to compare them.
- Total requests
- 1.2M +12.5% vs previous period
- Tokens used
- 46B +15.3% vs previous period
- Total cost
- $12,456.78 +8.3% vs previous period
- Avg latency
- 245 ms −5.2% vs previous period
- Error rate
- 0.80% −0.3% vs previous period
| Compare | Model | |||||
|---|---|---|---|---|---|---|
| gpt-4-turbo | 456,789 | 15B | 320 ms | $5,678.90 | 0.50% | |
| claude-3-opus | 123,456 | 8B | 280 ms | $3,456.78 | 0.40% | |
| gpt-3.5-turbo | 567,890 | 20B | 180 ms | $2,345.67 | 0.80% | |
| claude-3-sonnet | 89,012 | 2.5B | 220 ms | $875.43 | 1.20% | |
| gemini-pro | 8,531 | 0.17B | 200 ms | $100.00 | 1.50% |
- Cost per 1K requests$12.43$28.00
- Tokens per request32,83864,800
- Avg latency320 ms280 ms
- Error rate0.50%0.40%
Lower is better on every row. Sample data.
LLM Observability, screen by screen.
Real screens from the Atatus app.

Questions about LLM observability
Pricing, deployment, data and the agent. If something is missing, a person will answer it on a demo call.
Yes. Each LLM trace keeps the input and output of every step, so you can read what the model received and what it returned. Atatus stores what your application sends, so keep sensitive personal data out of prompts or mask it before it is sent. Data is kept for your plan's retention period and purged automatically after that.
LLM observability is part of the Atatus Python agent from version 2.1.0. Each call is recorded with its model provider and model name, for example OpenAI and Azure OpenAI models such as gpt-4o, Anthropic Claude models and Google Gemini. Flow View also draws each LLM provider your services call, such as openai or anthropic. For other languages, talk to us.
Atatus turns token usage into cost. The overview shows total requests, tokens used and total cost against the previous period, the model breakdown lists requests, tokens, latency, cost and error rate per model, and a daily cost chart covers the last 30 days.
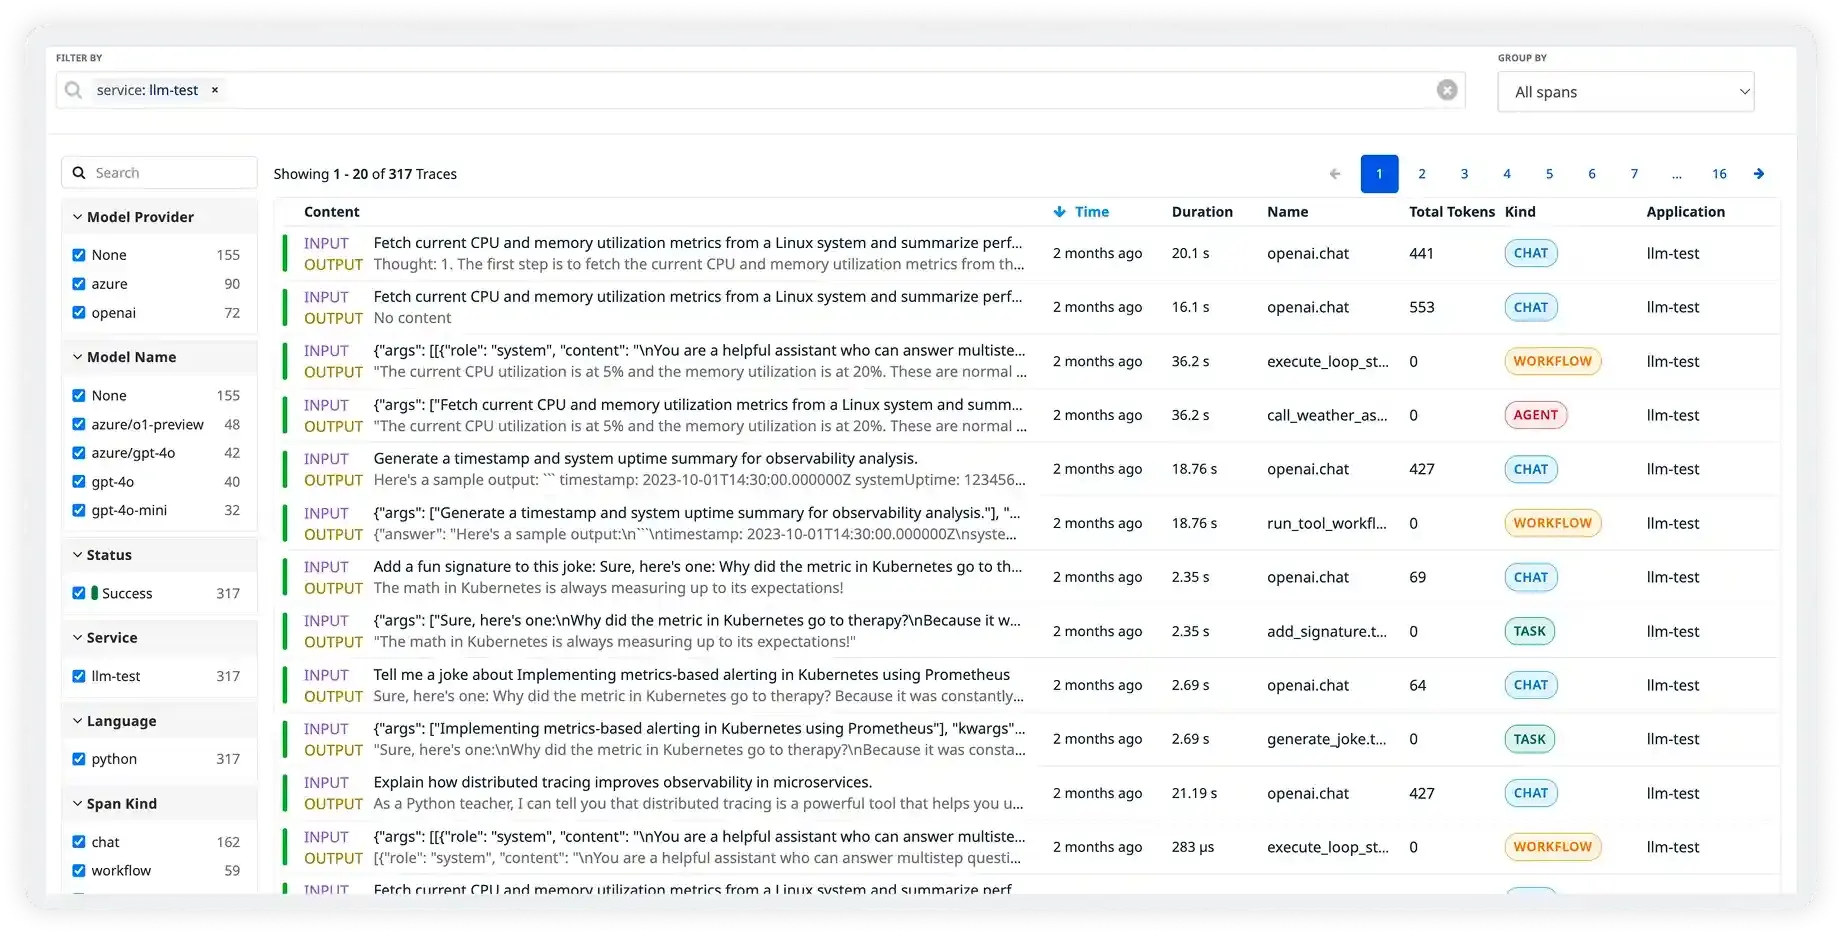
Yes. A trace records every step of an agent or chain as its own span, with the span kind (agent, workflow, task or chat), duration, total tokens, and input and output. The chain trace view lists each step in order, including the documents a retrieval step returned.
Yes. The model breakdown shows requests, tokens, average latency, cost and error rate for each model in the selected period, with higher error rates highlighted. You can also filter the traces list by model provider, model name, status, service, language and span kind.
Use Atatus Python agent 2.1.0 or later, which supports LLM Observability (llmobs). Your LLM calls then appear in the traces list with their input, output, duration and tokens, and roll up into the model breakdown and daily cost views.
Yes. Every new account gets a 14-day free trial, and no credit card is needed to start. After the trial, choose a plan that fits your volume. Atatus has no per-user pricing.
Trace each LLM call, see what it cost and compare models and providers side by side.
- SaaS
- On-premises
- Hybrid
- BYOC
- No per-user pricing
Compare Atatus with Datadog